Youngjoon Jang
M.S. Student at NLP&AI Lab, Korea University

Hi, I’m Youngjoon. I’m a Master’s student in NLP&AI Lab at Korea University, advised by Prof. Heuiseok Lim. Before this, I studied Mechanical Engineering & Computer Science at Hongik University.
I’m drawn to a deceptively simple question: “How can I help people find the right information?” This curiosity drives my work in Information Retrieval, Multilingual Information Retrieval, and Retrieval-Augmented Generation (RAG). My research has been published at SIGIR, ICLR, ACL, and EMNLP, while the Korean retrieval models and benchmarks I led have grown to 250+ GitHub stars and 3M+ downloads on Hugging Face.
I love building in the open, and I actively contribute to projects including Sentence-Transformers, MTEB, and InstructKR.
News
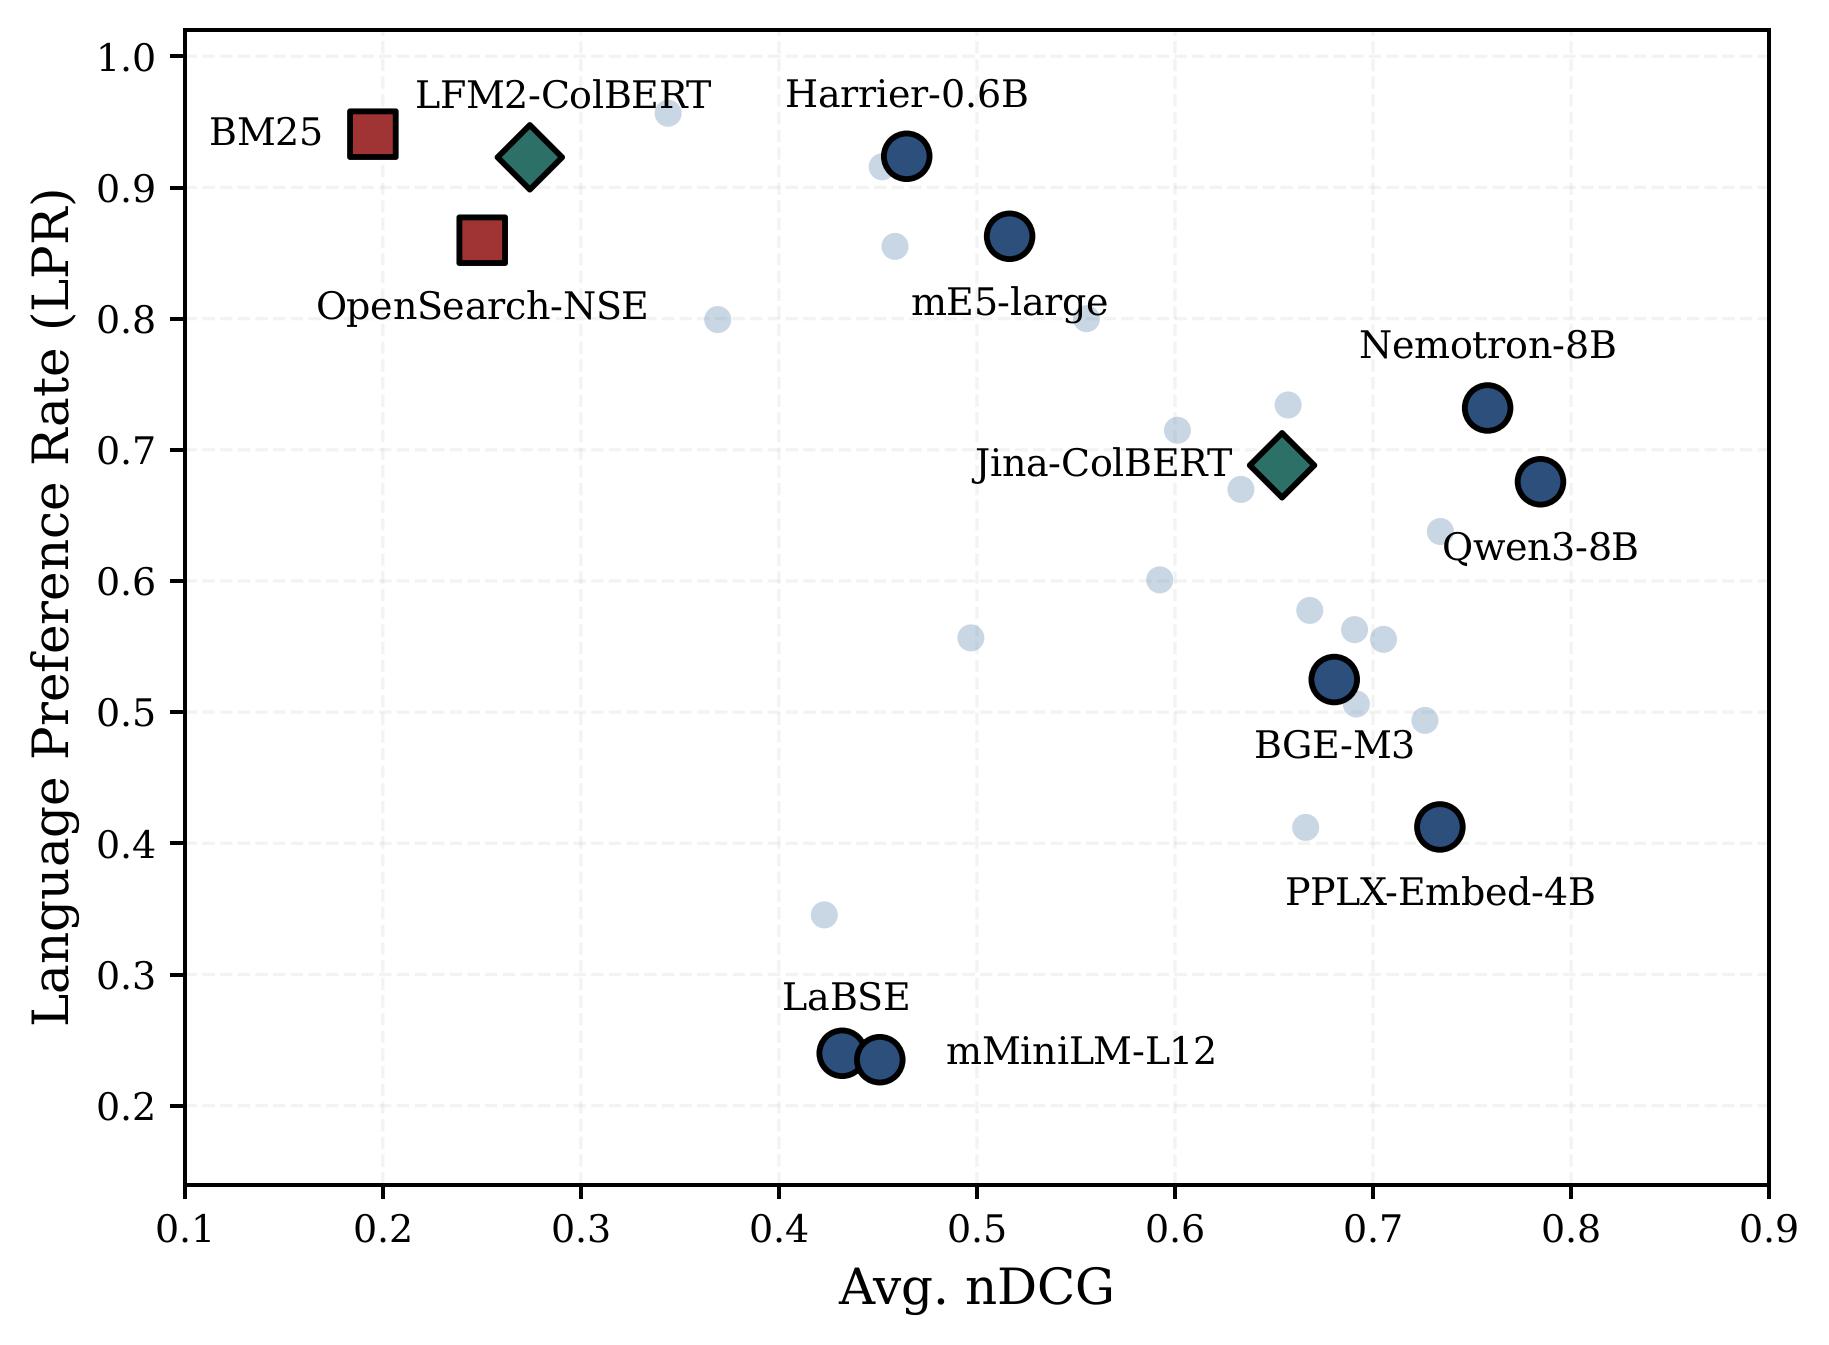
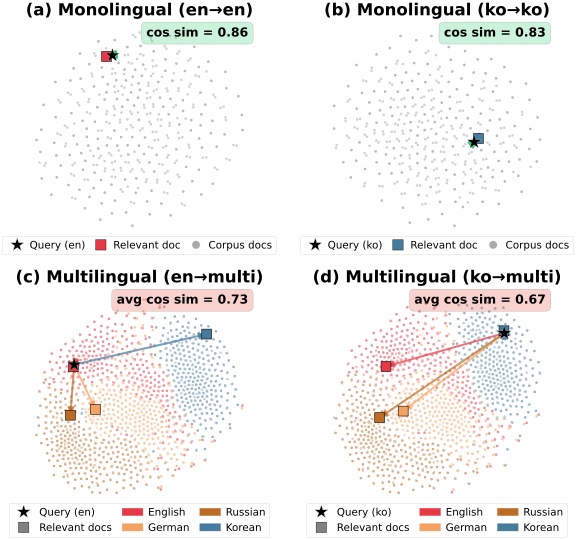
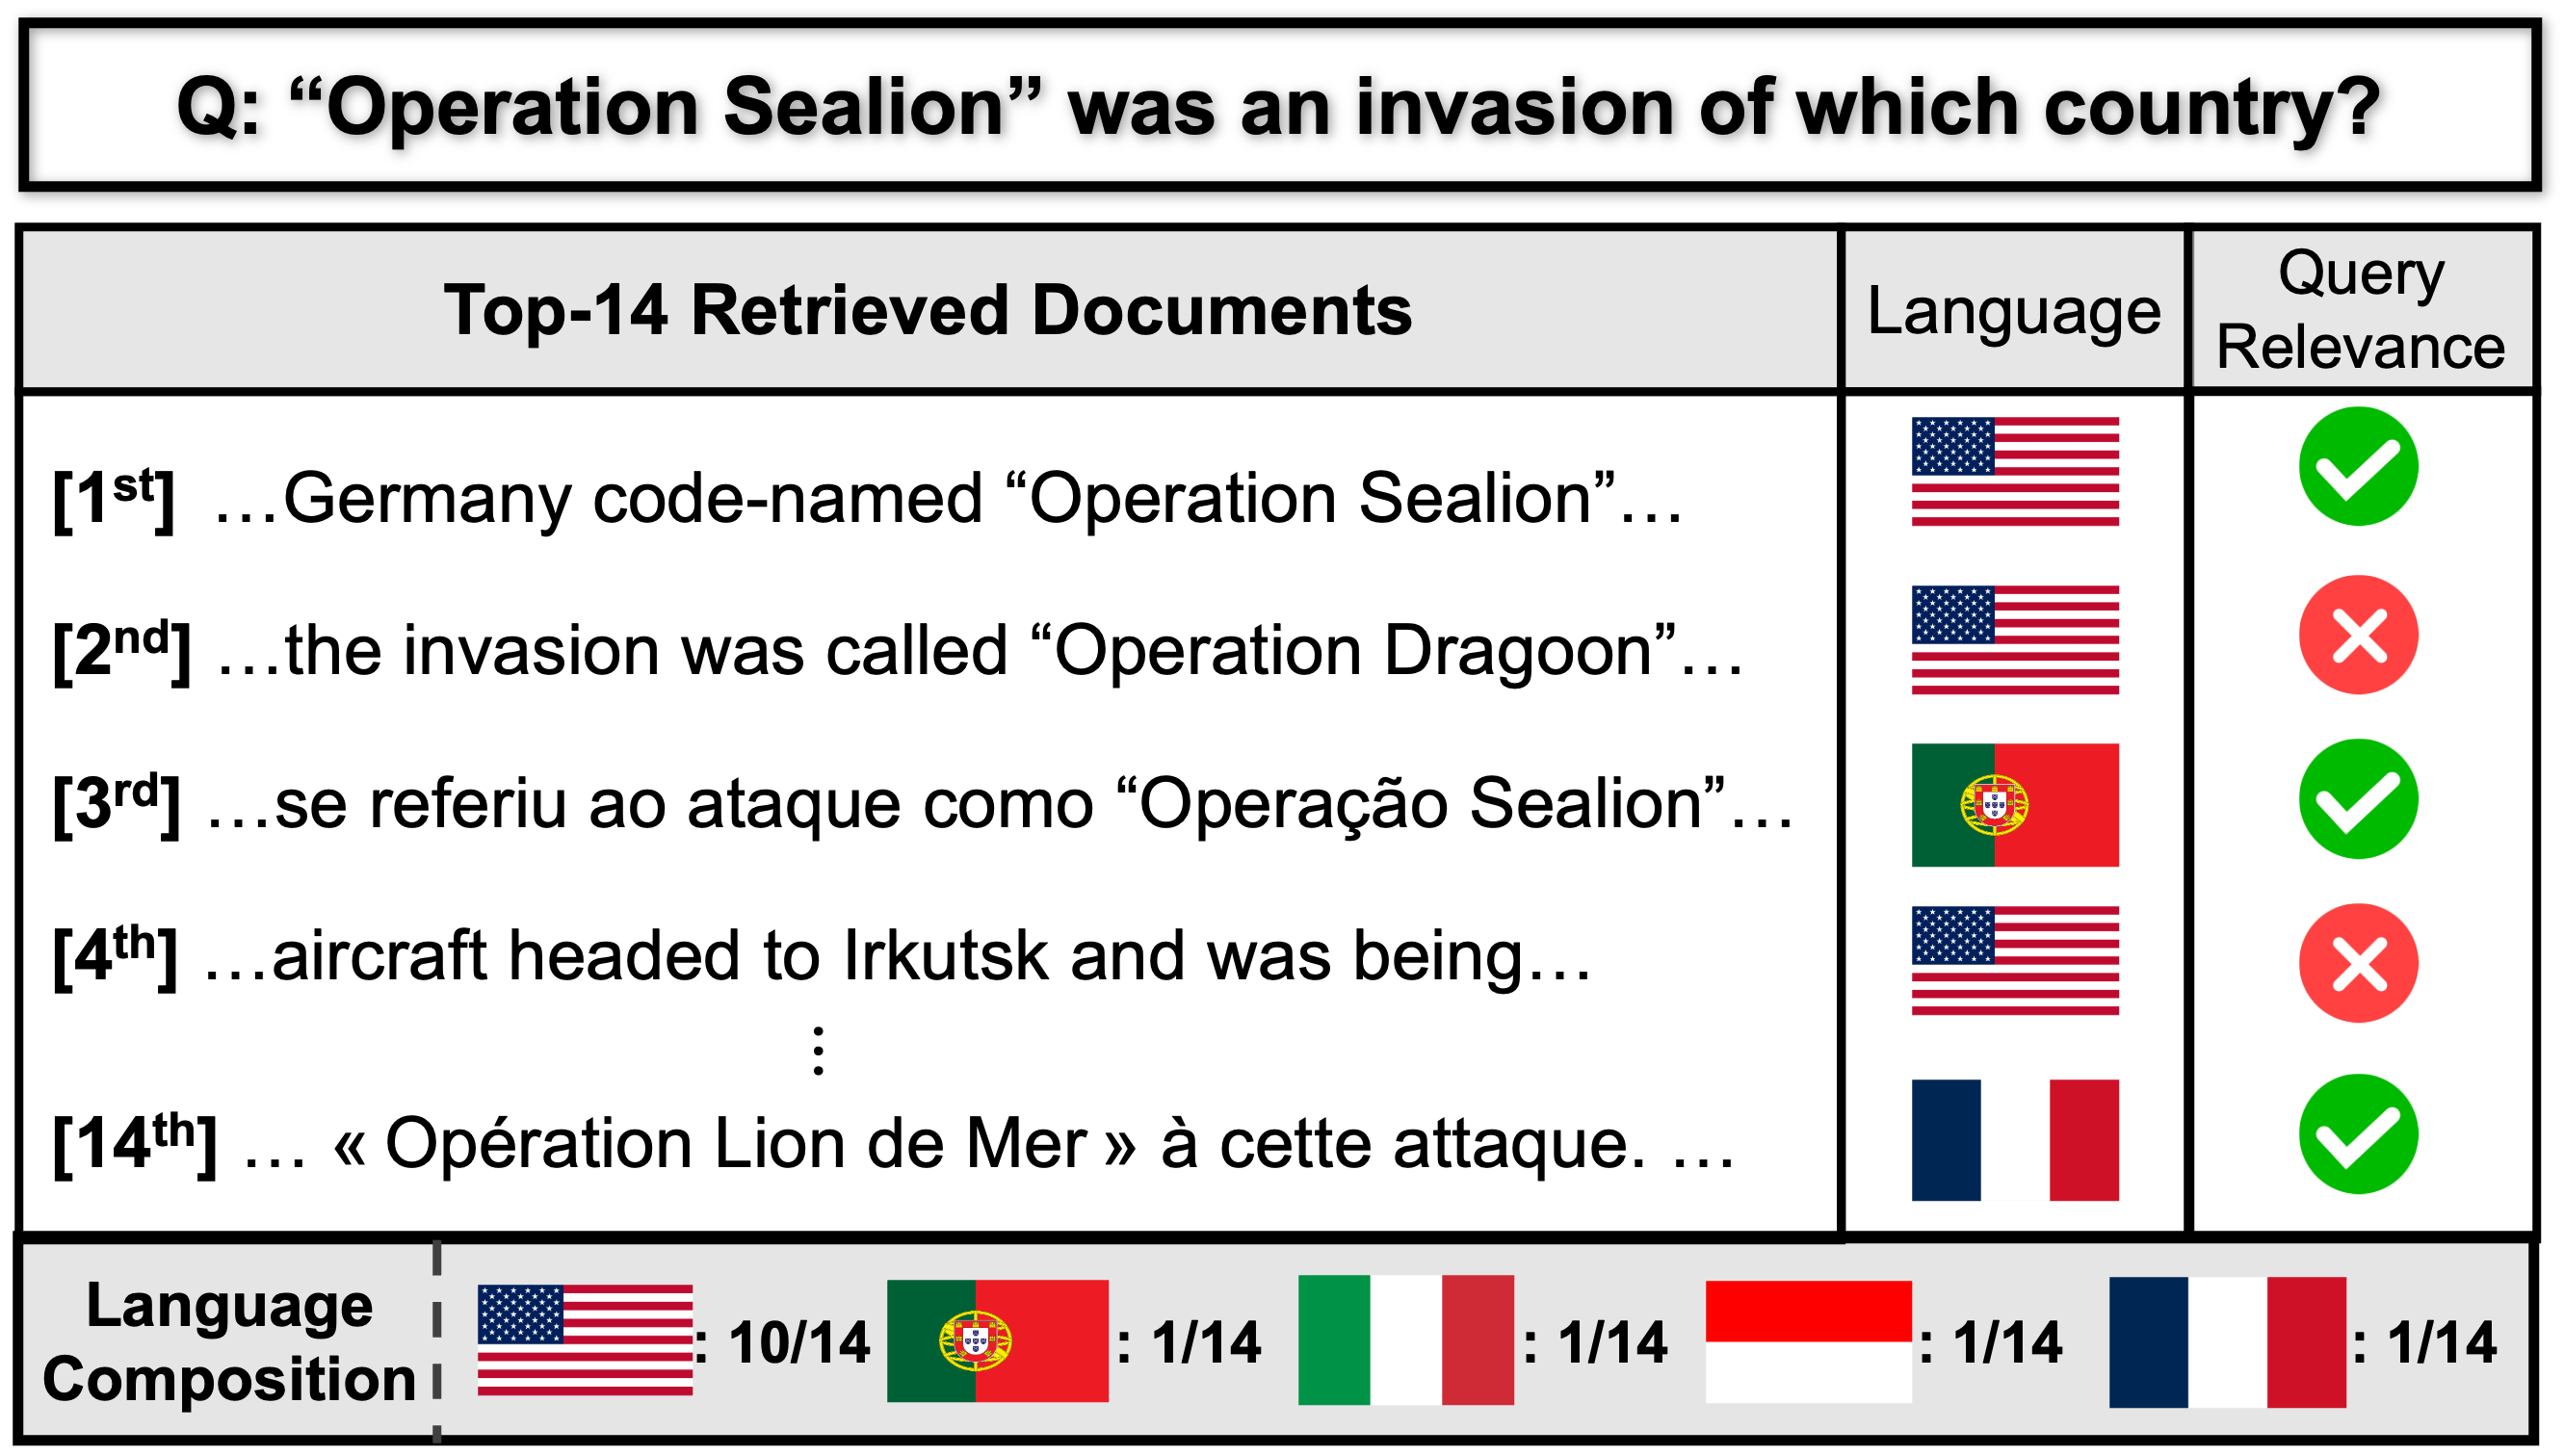
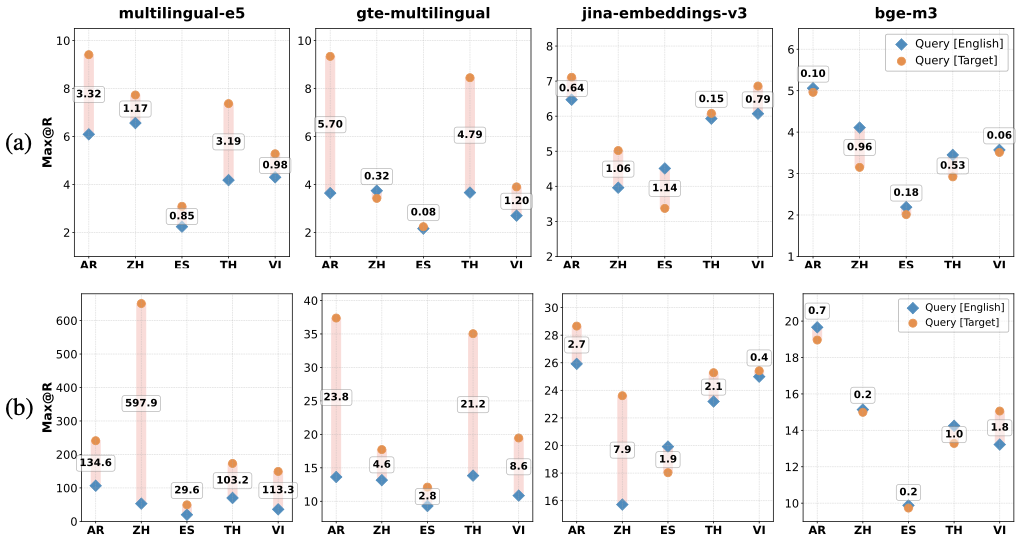
| Sep 26, 2026 | Our paper “MLAIRE: Multilingual Language-Aware Information Retrieval Evaluation Protocol” has been accepted to NeurIPS 2026 Evaluations & Datasets (E&D) Track 🇦🇺 |
|---|---|
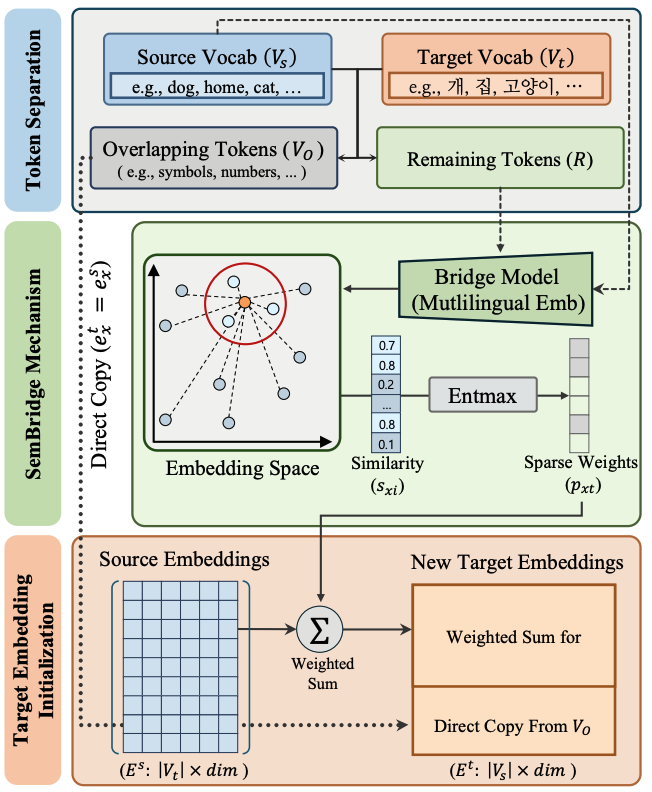
| Aug 21, 2026 | Our papers MIMO, SHIFT, and SemBridge have been accepted to EMNLP 2026 🇭🇺 |
Education
Projects
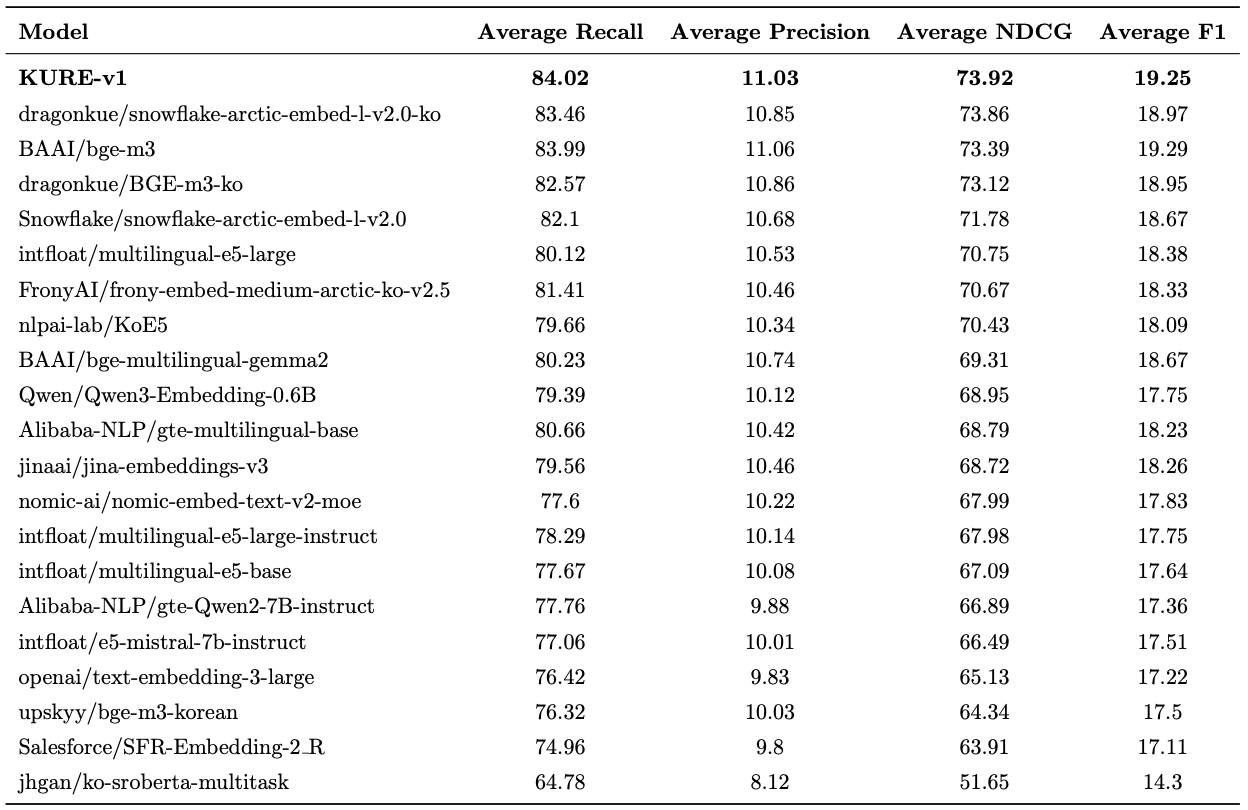
KURE: Korea University Retrieval Models (GitHub · HF · API)
Led the lab's flagship Korean–English retrieval project: built the MTEB-Ko-Retrieval leaderboard and open-sourced the model family with its training and evaluation code (250+ GitHub stars).
- Dense & Multi-Vector: KURE-v1 and KURE-v2 both ranked 1st on the leaderboard (as of Aug. 2025 and Oct. 2026, respectively), and KURE-v1 passed 3M downloads. KURE-v2, a multi-vector model, outperforms 8B dense models while being 50× smaller, and the newest KURE-v3 outperforms Qwen3-Embedding-8B while being 7× smaller.
- Sparse: KURE-Sparse-{base, nano}, state of the art in Korean sparse retrieval overall and under 0.5B parameters.
- Reranker: KURE-Reranker-{base, nano}, state of the art in Korean reranking under 4B and 1B parameters.
ReviewSearch (Blog · GitHub · Demo)
Built and deployed a search engine over 205,988 real peer reviews and rebuttals for agents, so that a rebuttal draft is grounded in how authors actually answered the same concern.
WBL: World Best LLM Project (HF)
Led the data team: built a query-clarity tagging & evaluation framework, and a reward-model-ensemble response-filtering pipeline for large-scale training data.
URACLE–Korea University Collaborative Research
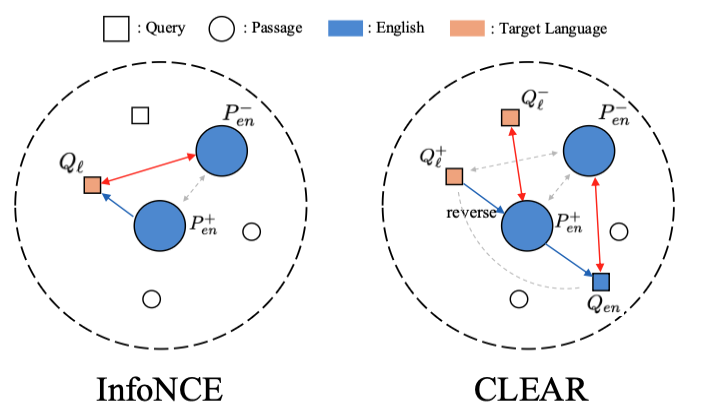
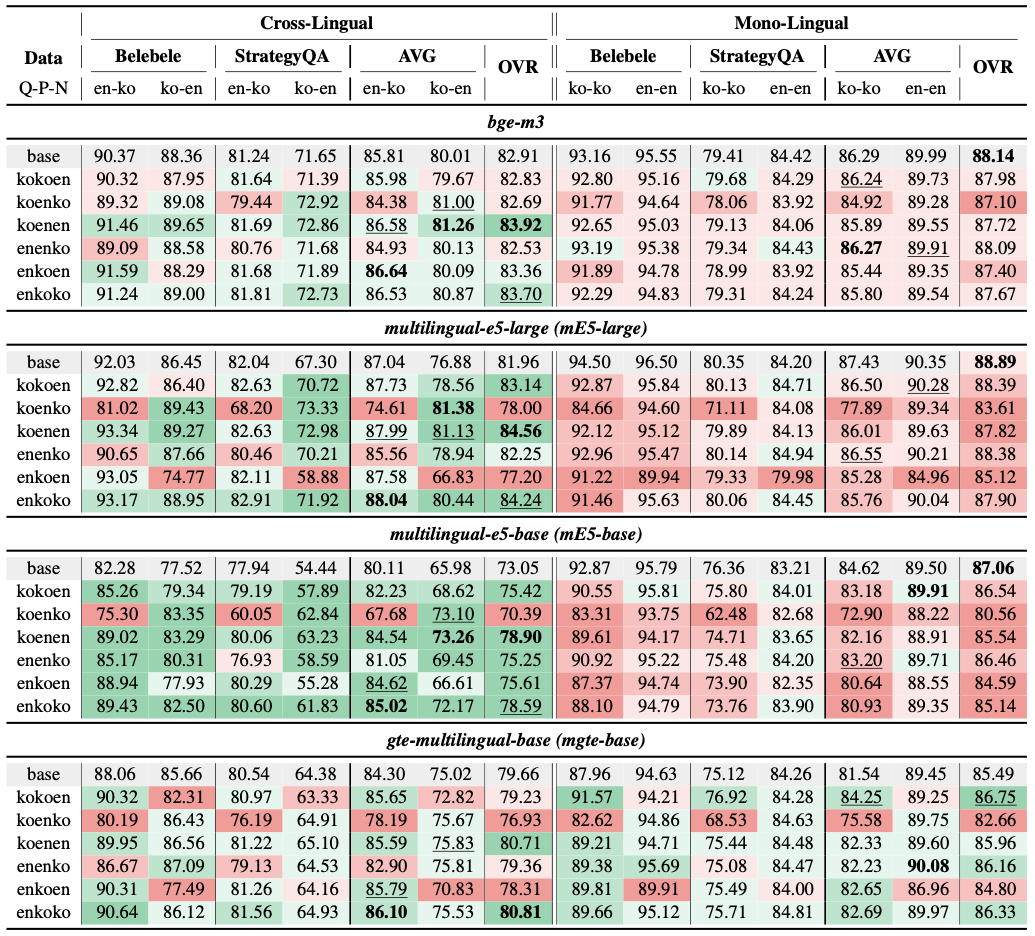
Trained a Korean–English cross-lingual retriever and analyzed language-pair trade-offs. Used model merging to recover monolingual retrieval while retaining cross-lingual retrieval gains. Published in the ACL 2026 MeLLM Workshop.
KT–Korea University Collaborative Research (Korean Legal LLM) (News)
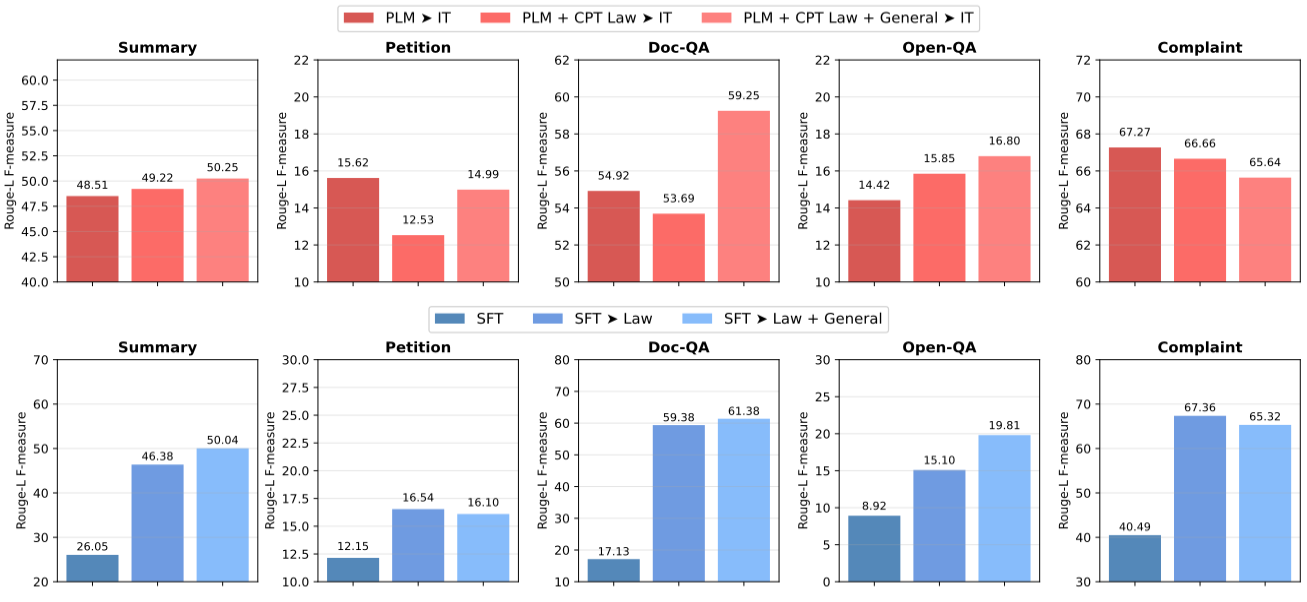
Developed an end-to-end training recipe for a Korean legal-domain LLM, published as LEGALMIDM (ICLR 2026 Data-FM Workshop). Contributed to KT's $10.42M contract for the South Korean Supreme Court AI platform.
Open Source Contributions
- Extended the cross-encoder training stack with classic learning-to-rank losses. [PR #6] [PR #7]
- Implemented EmbedDistillLoss to support direct embedding-level knowledge distillation. [PR #3665]
- Introduced hardness-weighted contrastive learning to up-weight informative hard negatives. [PR #3667]
- Implemented CachedSpladeLoss for gradient-cache compatible, memory-efficient SPLADE training. [PR #3670]
- Added mergekit-based model merging for dense, sparse, and cross-encoder models. [PR #3776]
- Added a Korean retrieval benchmark task to expand multilingual retrieval evaluation. [PR #1388]
- Improved stability of the OpenAI embeddings by adding sentence trimming. [PR #1526]
- Fixed NaN embeddings for Jasper models by switching model precision. [PR #2481]
- Led the Korean Reranker evaluation and leaderboard project. [GitHub]
Publications [International Conference]
Publications [Domestic Conference]

Preprint
-
- Under Review*Corresponding author
-